3日目: Project Hail Mary, Peer Review and ICSE'2025 papers
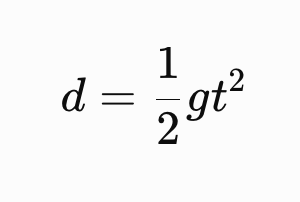
I promised L that I would read Project Hail Mary while in Japan.
I have been trying to avoid reading English in favour of reading in Japanese. Nonetheless I started reading it. And I got hooked.
I wonder how many people read about the height of the table (0.91m) and the average time it takes for something to drop from it (0.348s) and get a piece of paper to compute the g.
Today I read the following sentence: "Peer review may have fallen by the wayside, but at least I could self-review. Better than nothing"
It reminds me of the current trend today in computer science to cite ArXiv instead of a peer-reviewed paper. The main motivation is that AI (specially Agentic) is moving soo fast, that by the time papers get published, they are "Dead on Arrival"
Heiko Koziolek did a great analysis of the papers:
https://www.linkedin.com/posts/heiko-koziolek-613a2a6_icse-2026-what-actually-matters-for-a-working-activity-7451993258353942530-k8Lz
… roughly one in three research-track papers and about half the SEIP papers touch LLMs for code, agents, or evaluation
[…]
(2) Half the Research-Track LLM work is already obsolete on arrival. Papers benchmarked on GPT-4o, Claude 3.5/3.7 Sonnet, Gemini 2.0, and DeepSeek-V3 were camera-ready before Claude Sonnet 4.5 (Sep 29, 2025), MindStudio Skywork GPT-5 (Aug 7, 2025), Botpress +2 GPT-5.2-Codex (Dec 2025), OpenAI GPT-5.3-Codex (Feb 2026), OpenAI Gemini 3 Pro (Nov 18, 2025), InfoQ +7 and Cursor 2.0/Composer (Oct 29, 2025) Medium CometAPI shipped. SWE-bench Verified jumped from ~45% to 82% in that window. Leanware Any "our prompting scheme beats GPT-4o by 7 points" paper is now a historical artifact.
I guess it is up to us (me) to make sure the work in ArXiv is good
I am enjoying the book. Weir has a way of using science to make me laugh. He writes for scientists. All You Need is Kill will have to wait.